
Automation
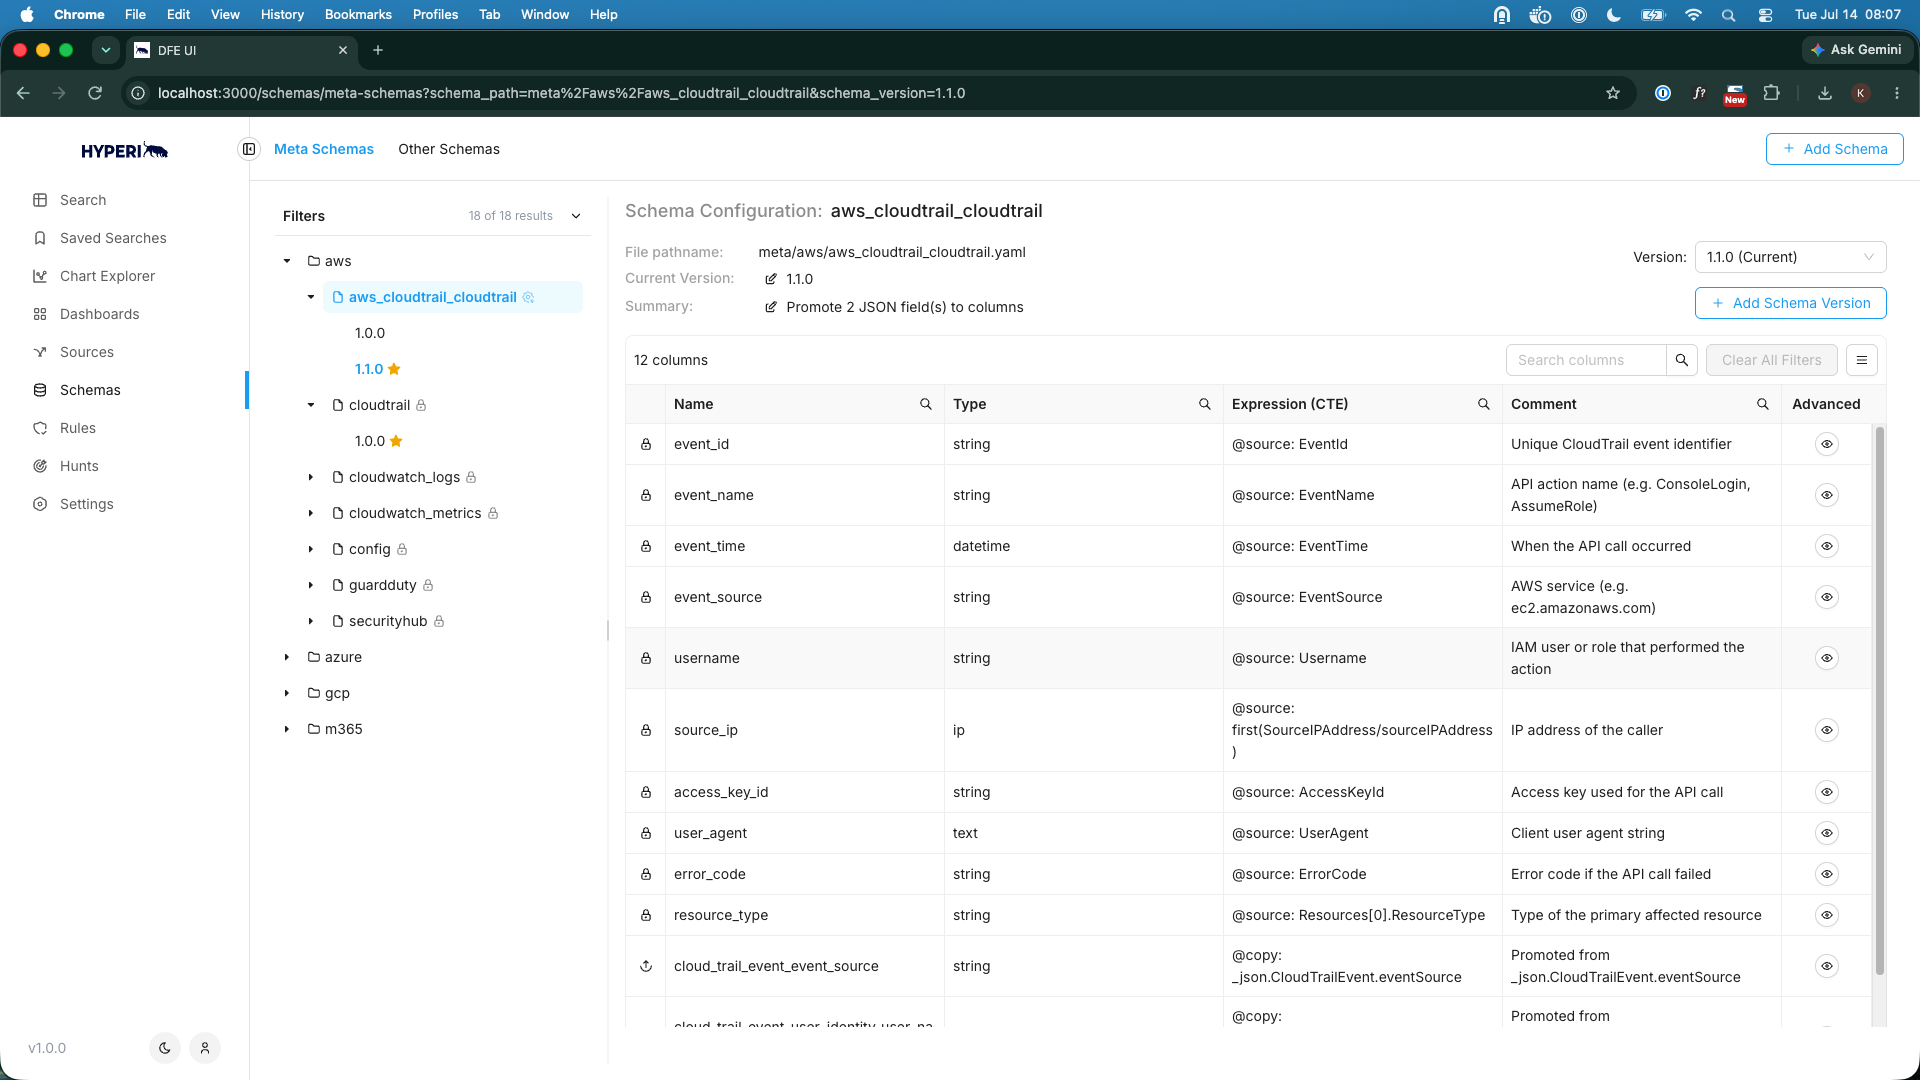
Build schemas in minutes, not months
Plan, build, and deploy data schemas across your environment with a structured, repeatable workflow.
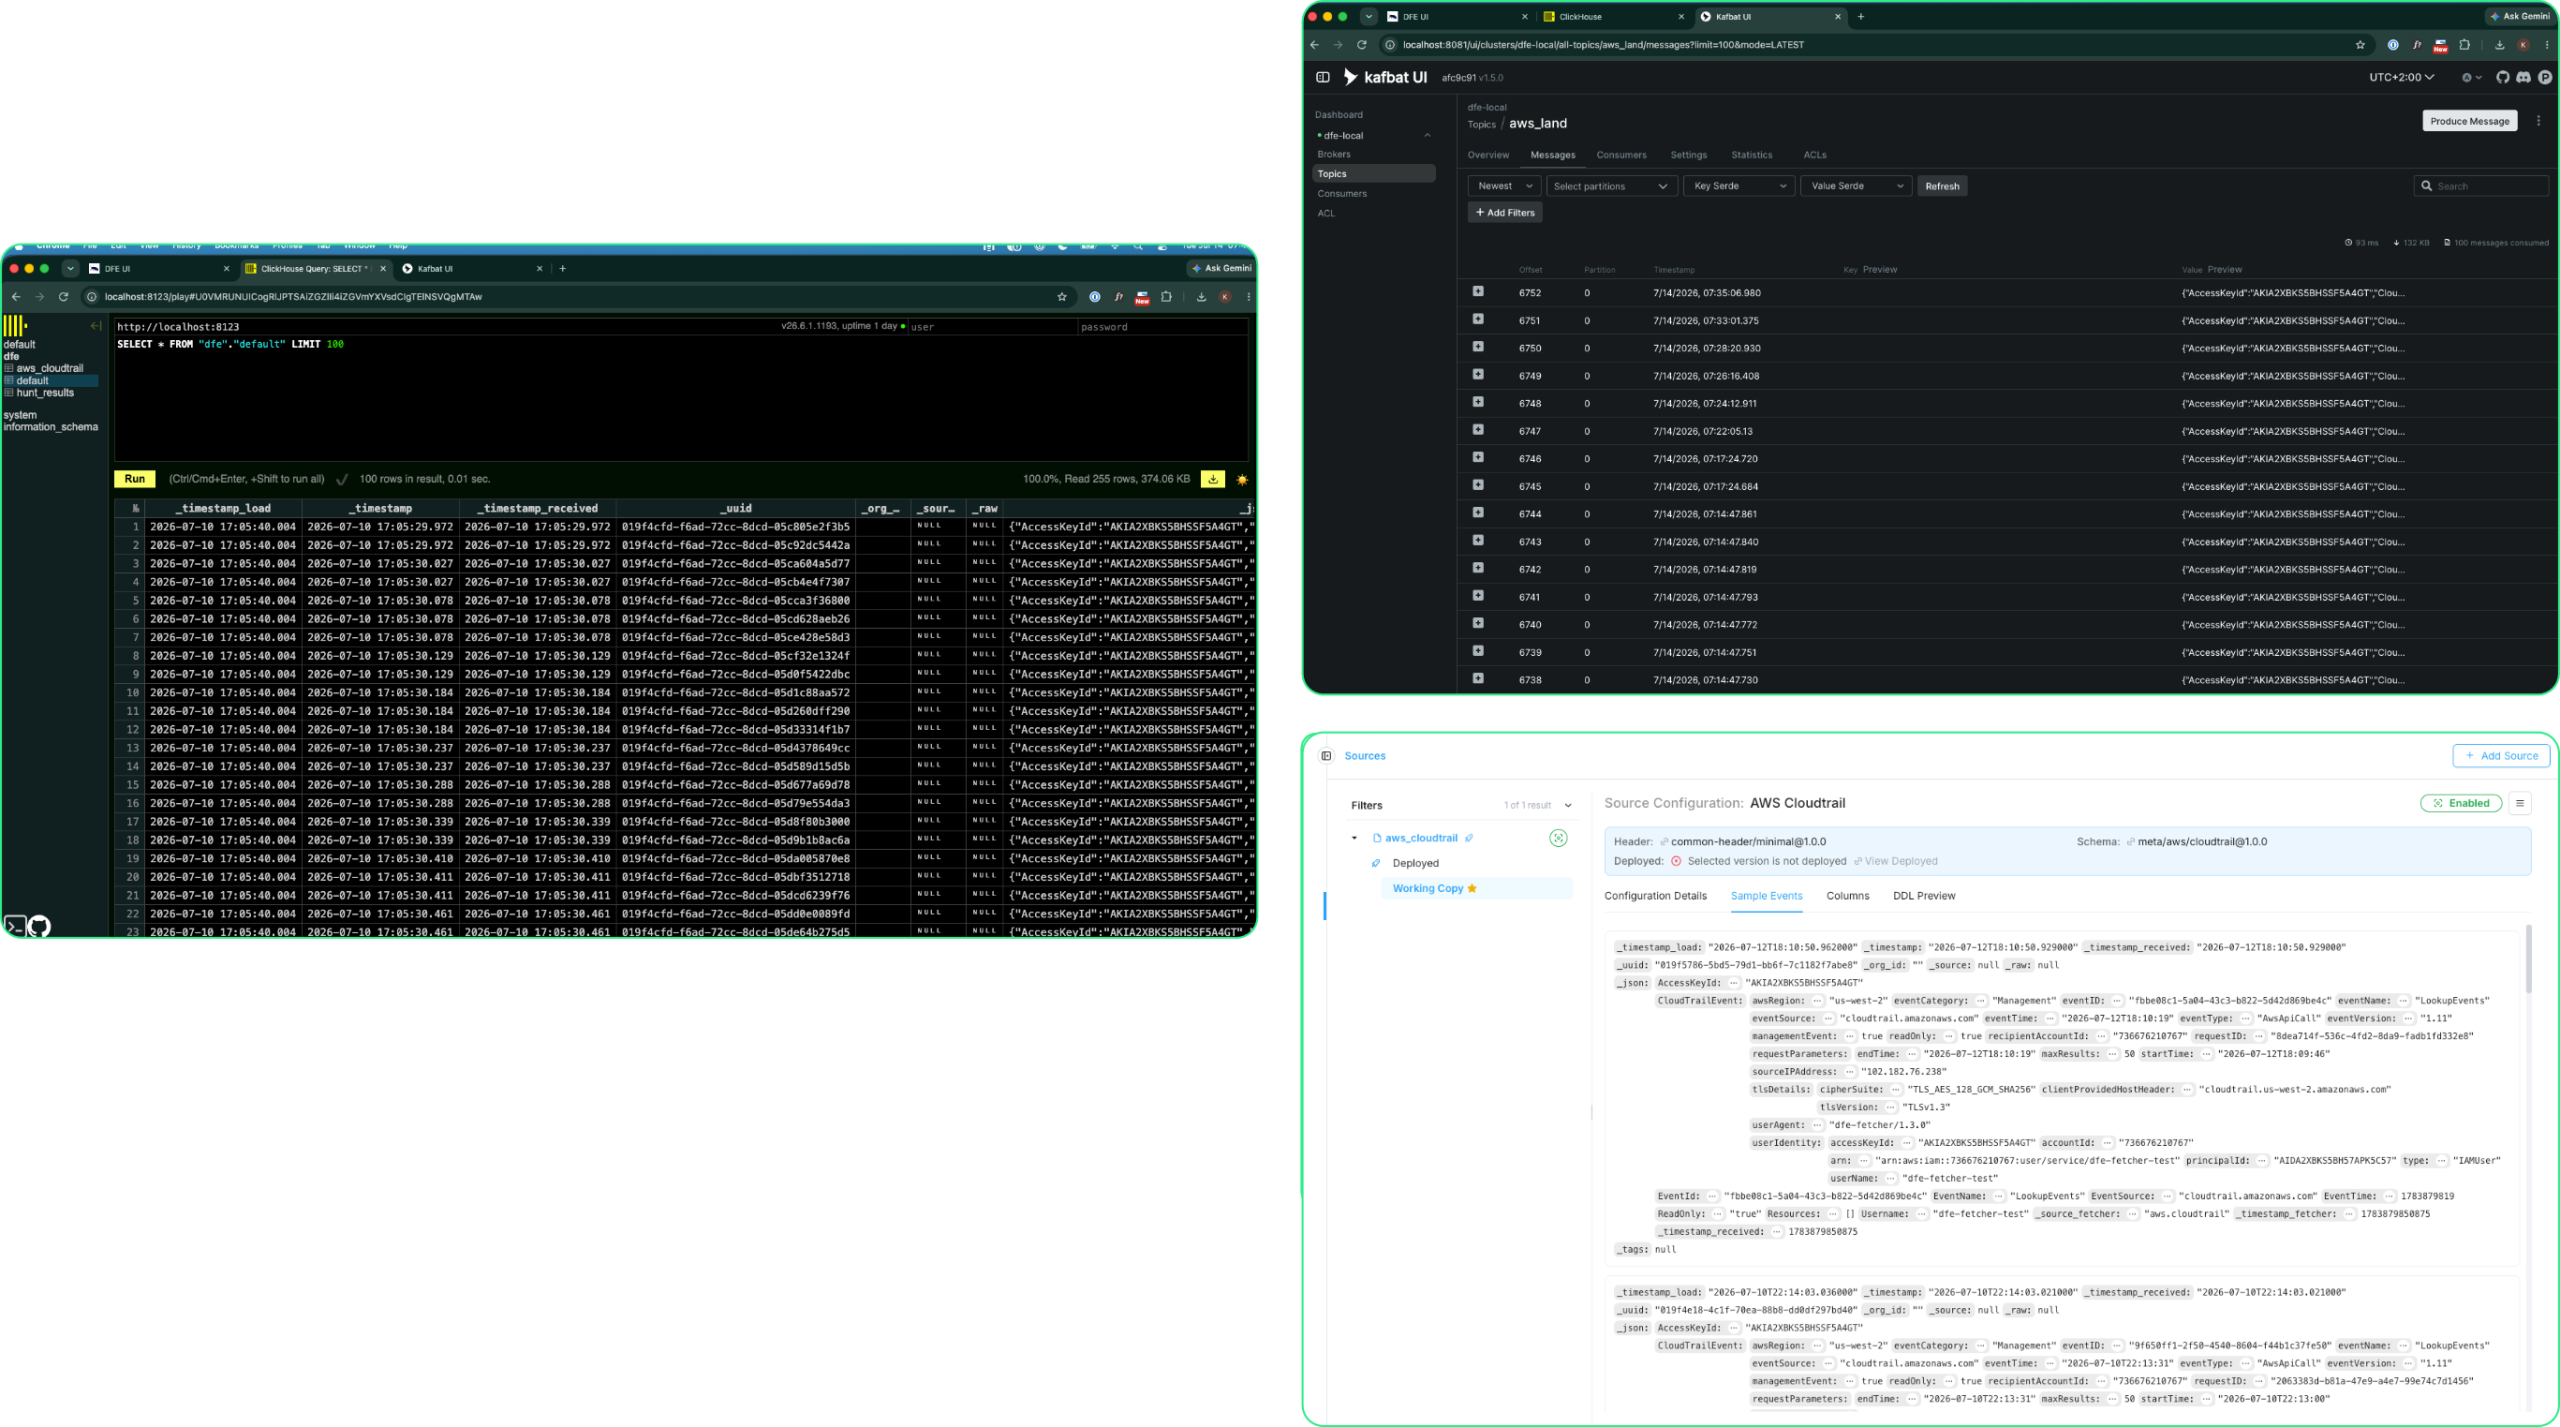
Plan, build, and deploy in a guided three-step process
Version-controlled schemas with full audit history
Deploy across multiple organisations simultaneously
Supports Syslog, Filebeat, Windows, CEF and more
Deployment
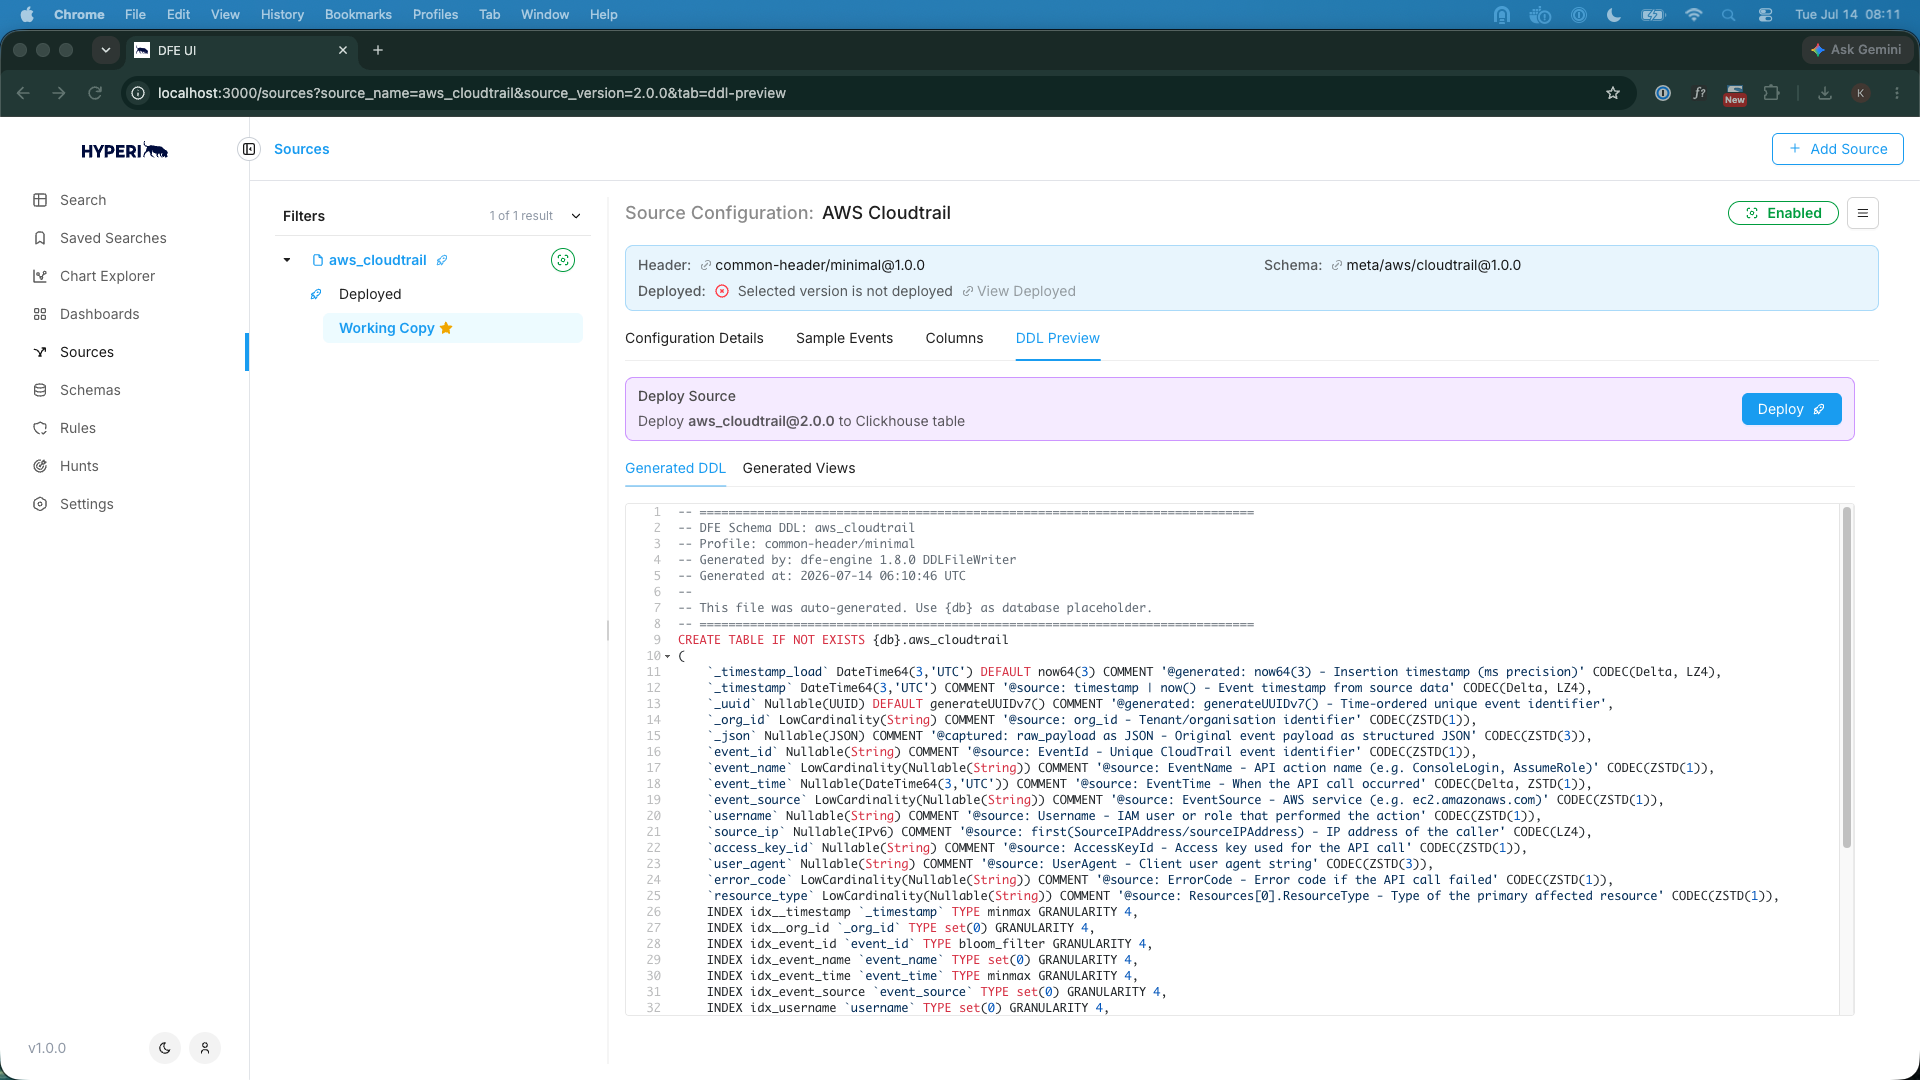
Deploy across your entire environment in one action
Apply schema changes to multiple organisations instantly — use the latest build or pin a specific release.
Apply to all organisations or target specific tenants
Deploy multiple built schemas in a single operation
Use latest build or pin to a specific version
Reduces integration time from months to days
Hunting & Alerting
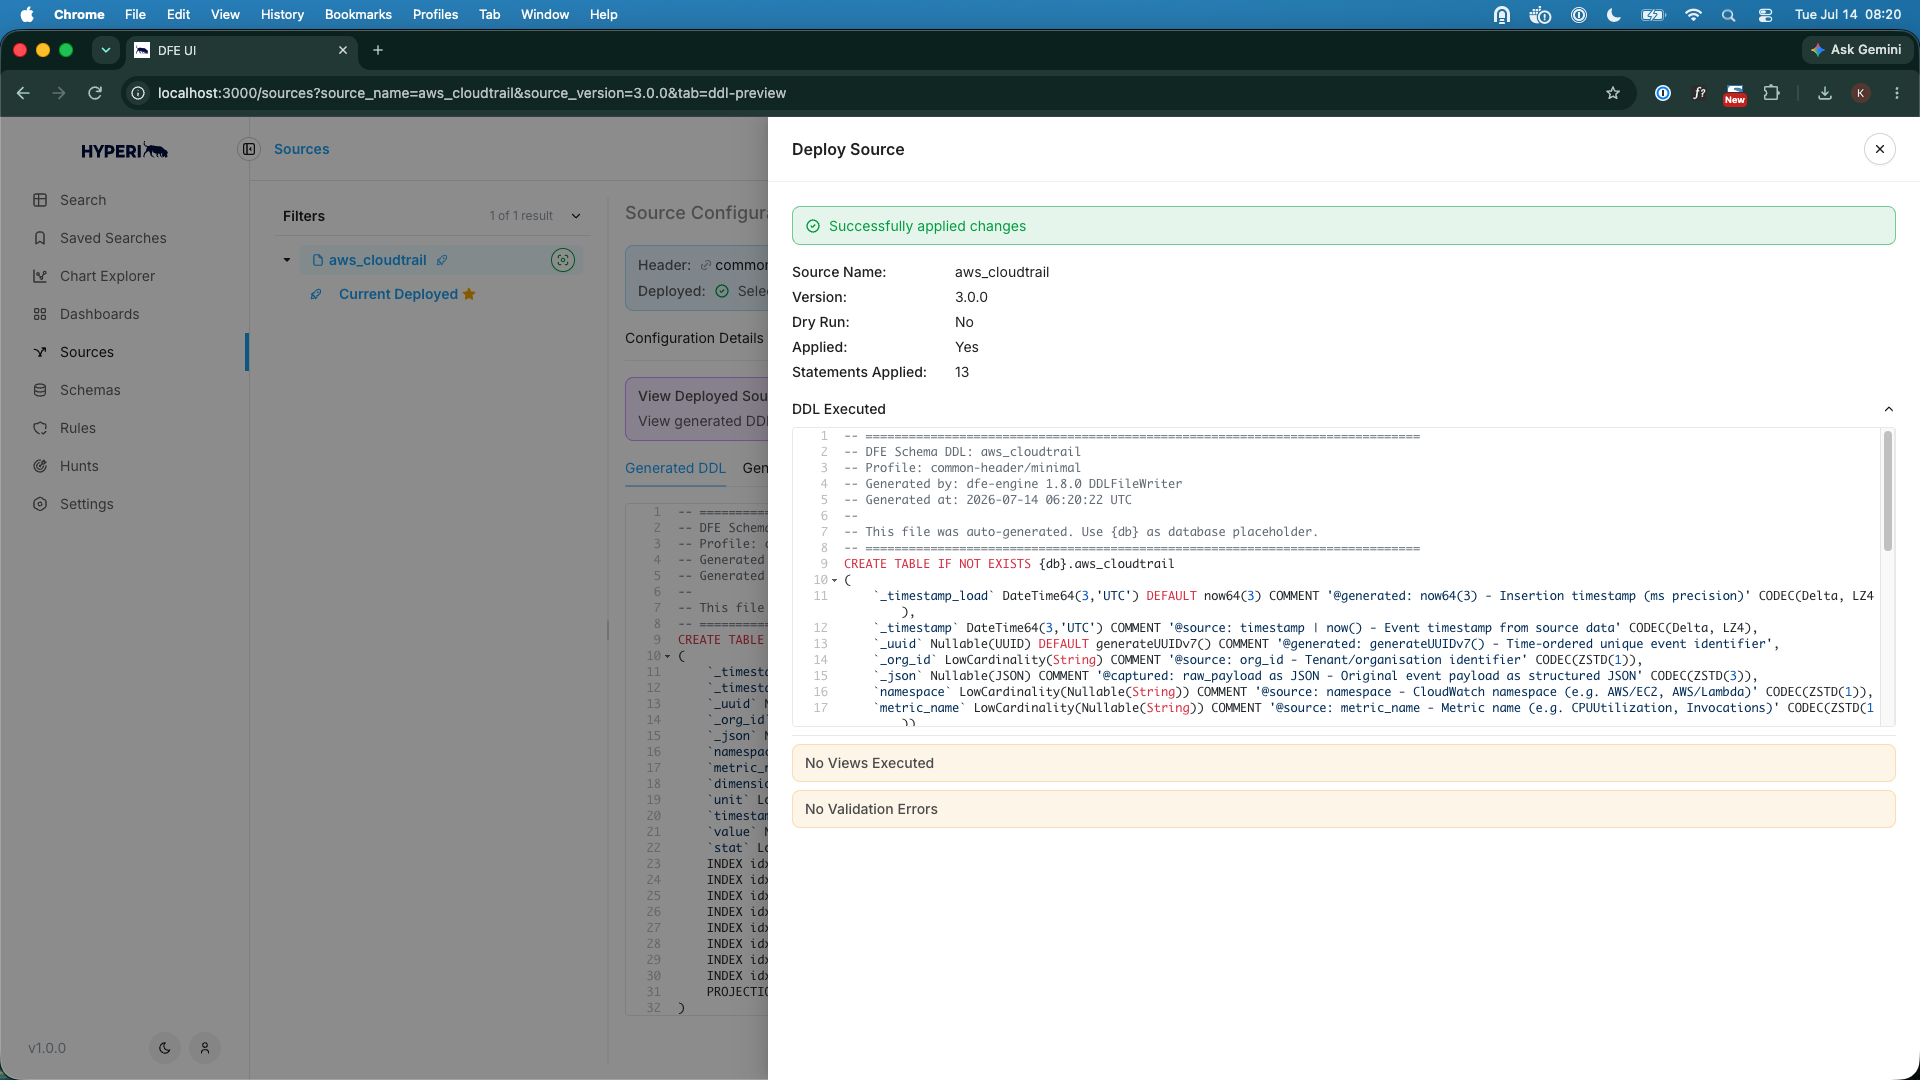
Real-time detection with custom SQL hunt rules
Write and deploy custom detection rules directly against your data pipelines with full SQL flexibility.
Custom SQL hunt queries against live data
Severity, schedule, and remediation steps per rule
Scoped per schema — precise, low-noise detection
Real-time visibility into threat activity
Schema Management
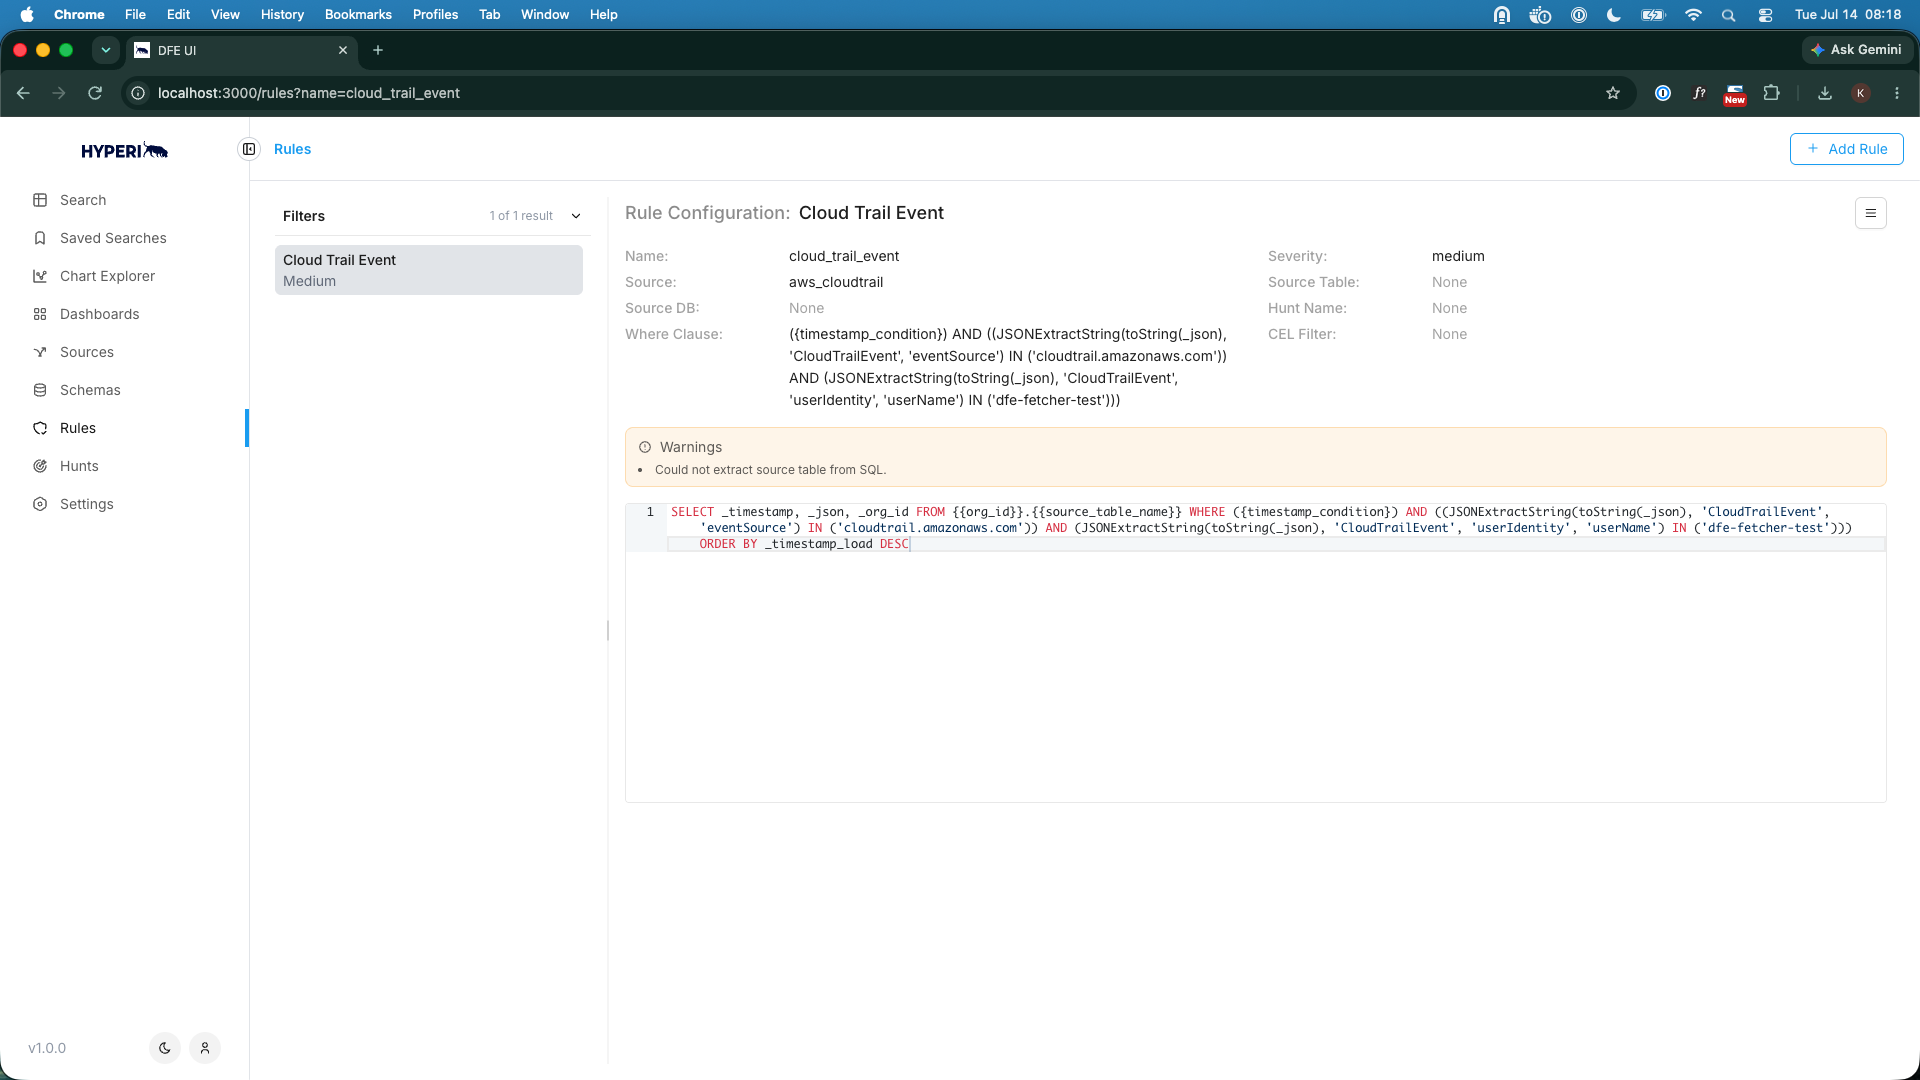
Manage and version your data schemas centrally
Upload, compare, and manage meta schemas and derived schemas from a single interface with full version history.
Upload Meta Schemas via CSV or Elastic Index Template
Create derived schemas from a base meta schema
Compare versions with a built-in diff view
Full audit trail on every schema change
Improved Efficiency
Seamless Integration
Enhanced Threat Detection
Cost-Effective Scalability
Accelerated Response